Crawled. Cited?
See which AI bots read your site and which AI engines send people back, on any site and any stack. Add a script tag and a small Cloudflare Worker or server snippet, and the report is waiting in your dashboard.
Private beta · Cloudflare, PHP or Node · No cookies · On WordPress? There's a free plugin
Two numbers per bot
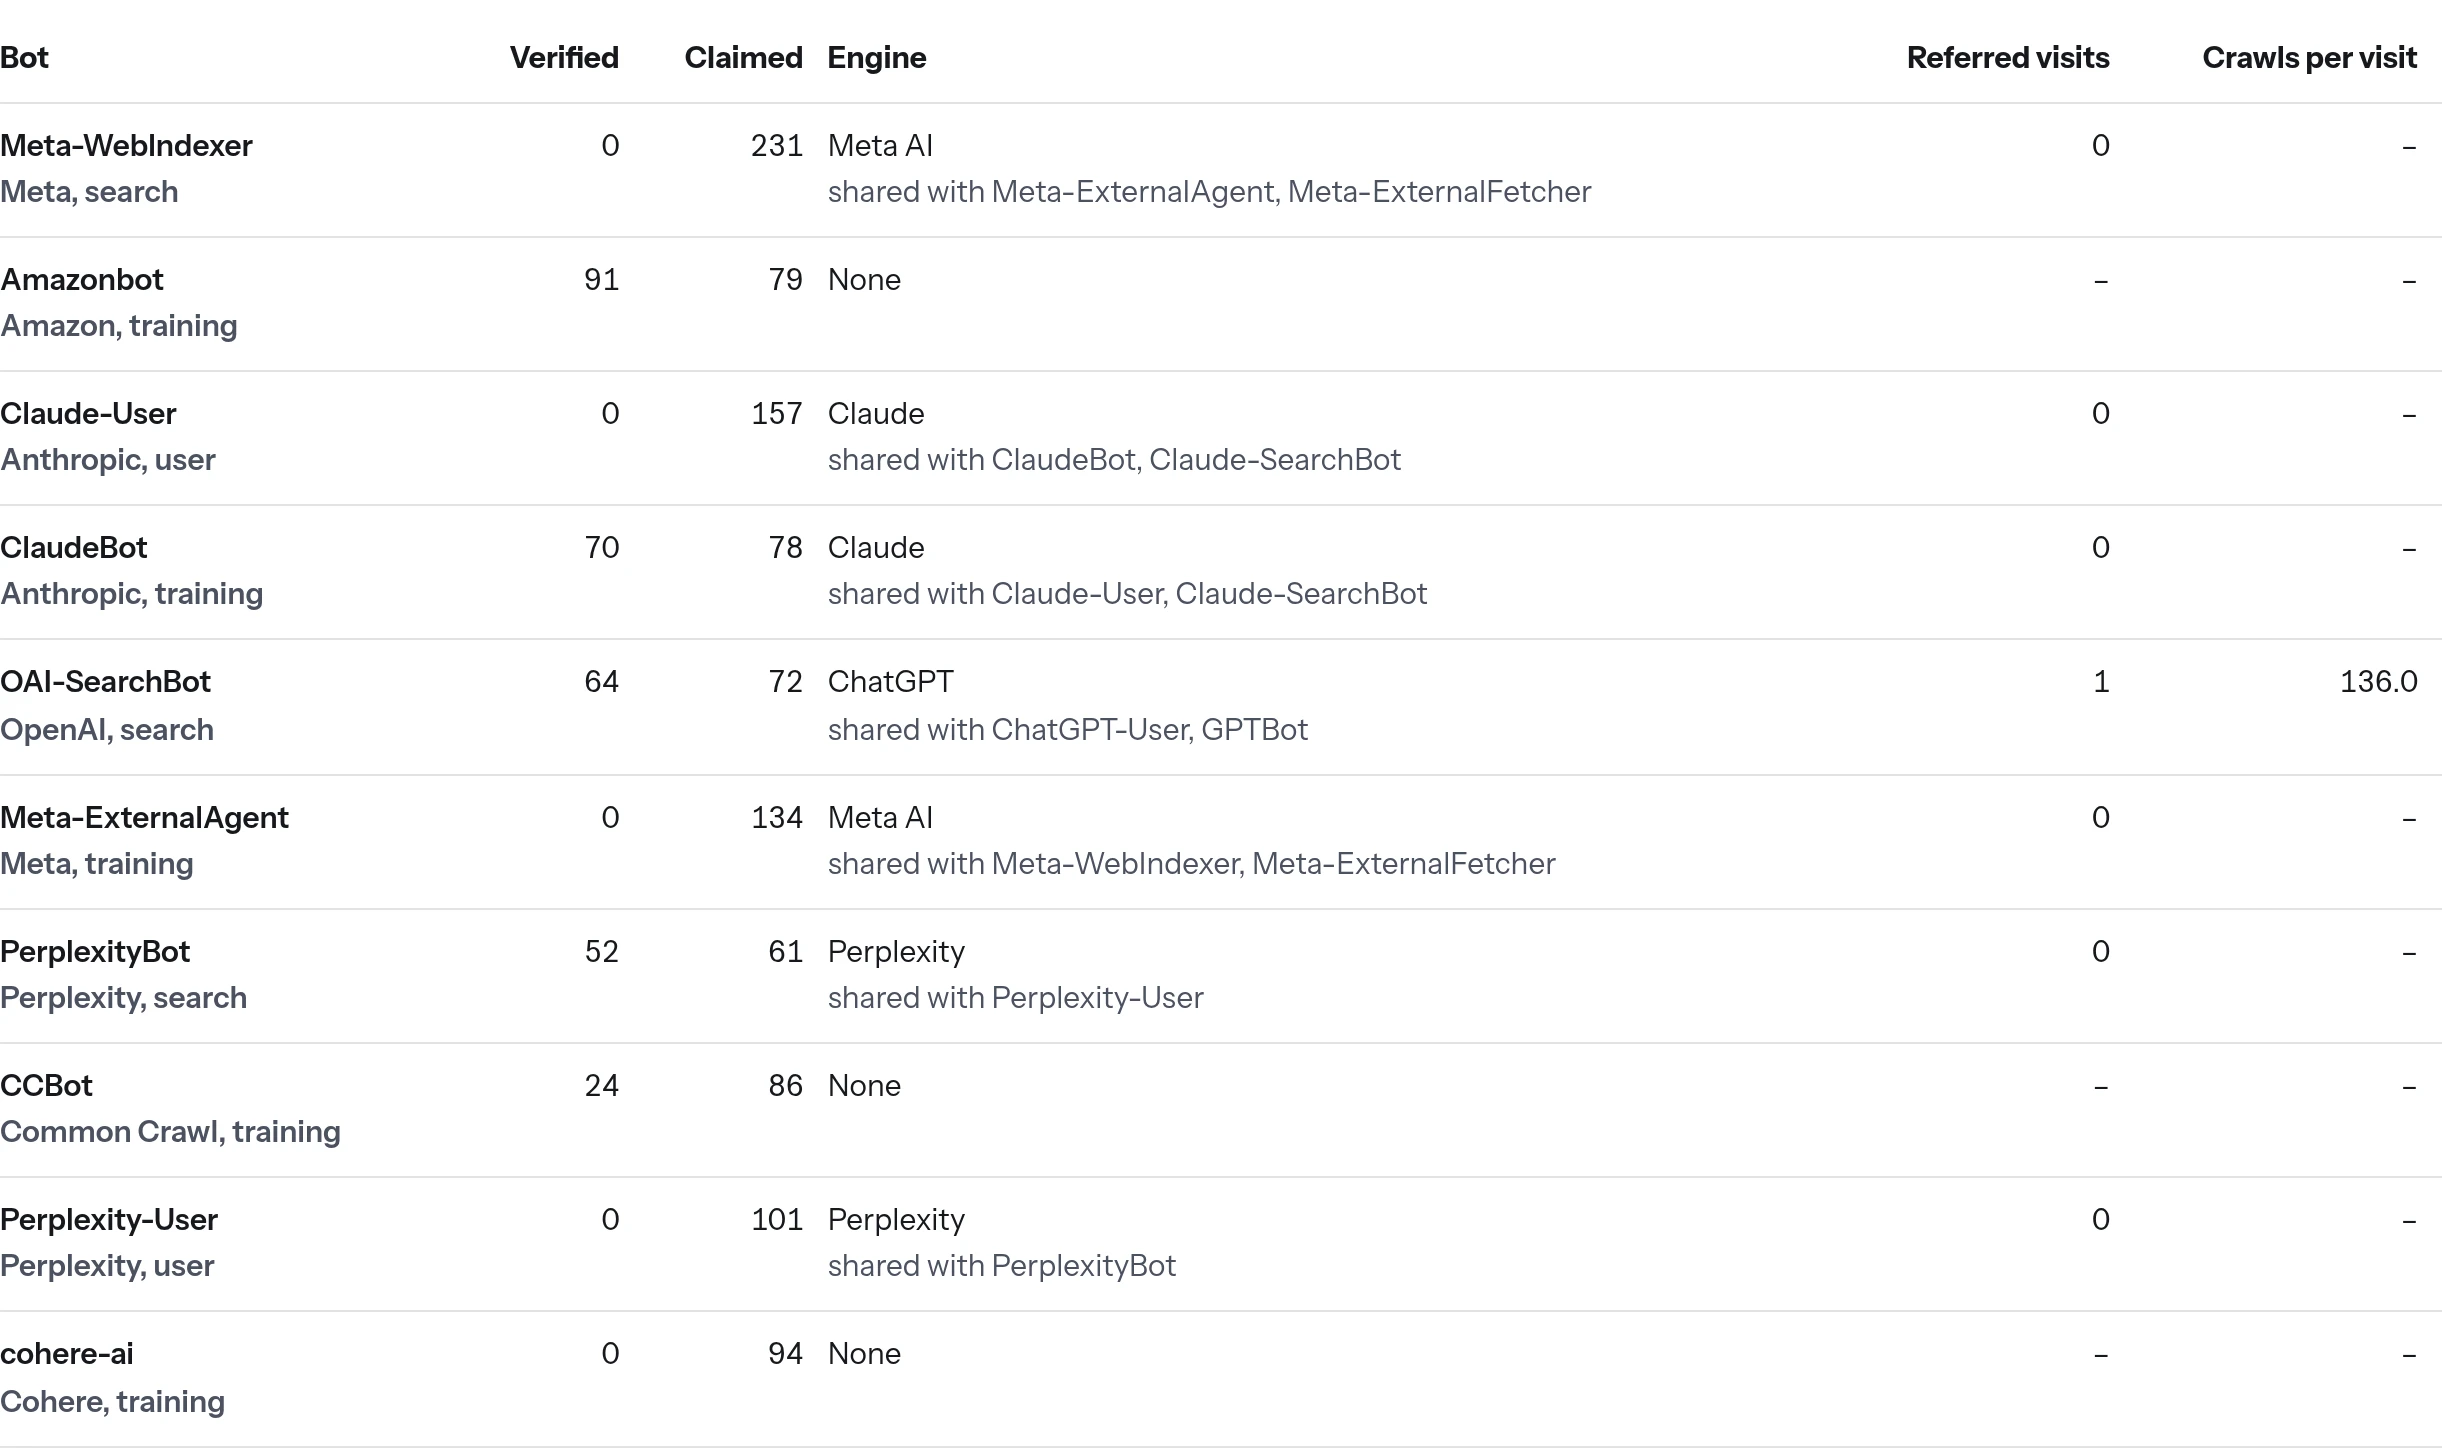
Crawl requests are pages a bot fetched from your site. Referred visits are people who clicked through to you from that company's AI engine. The dashboard puts them side by side for every bot, so you can see who reads a lot and sends nobody.
520
64
Example numbers. Yours will be different.
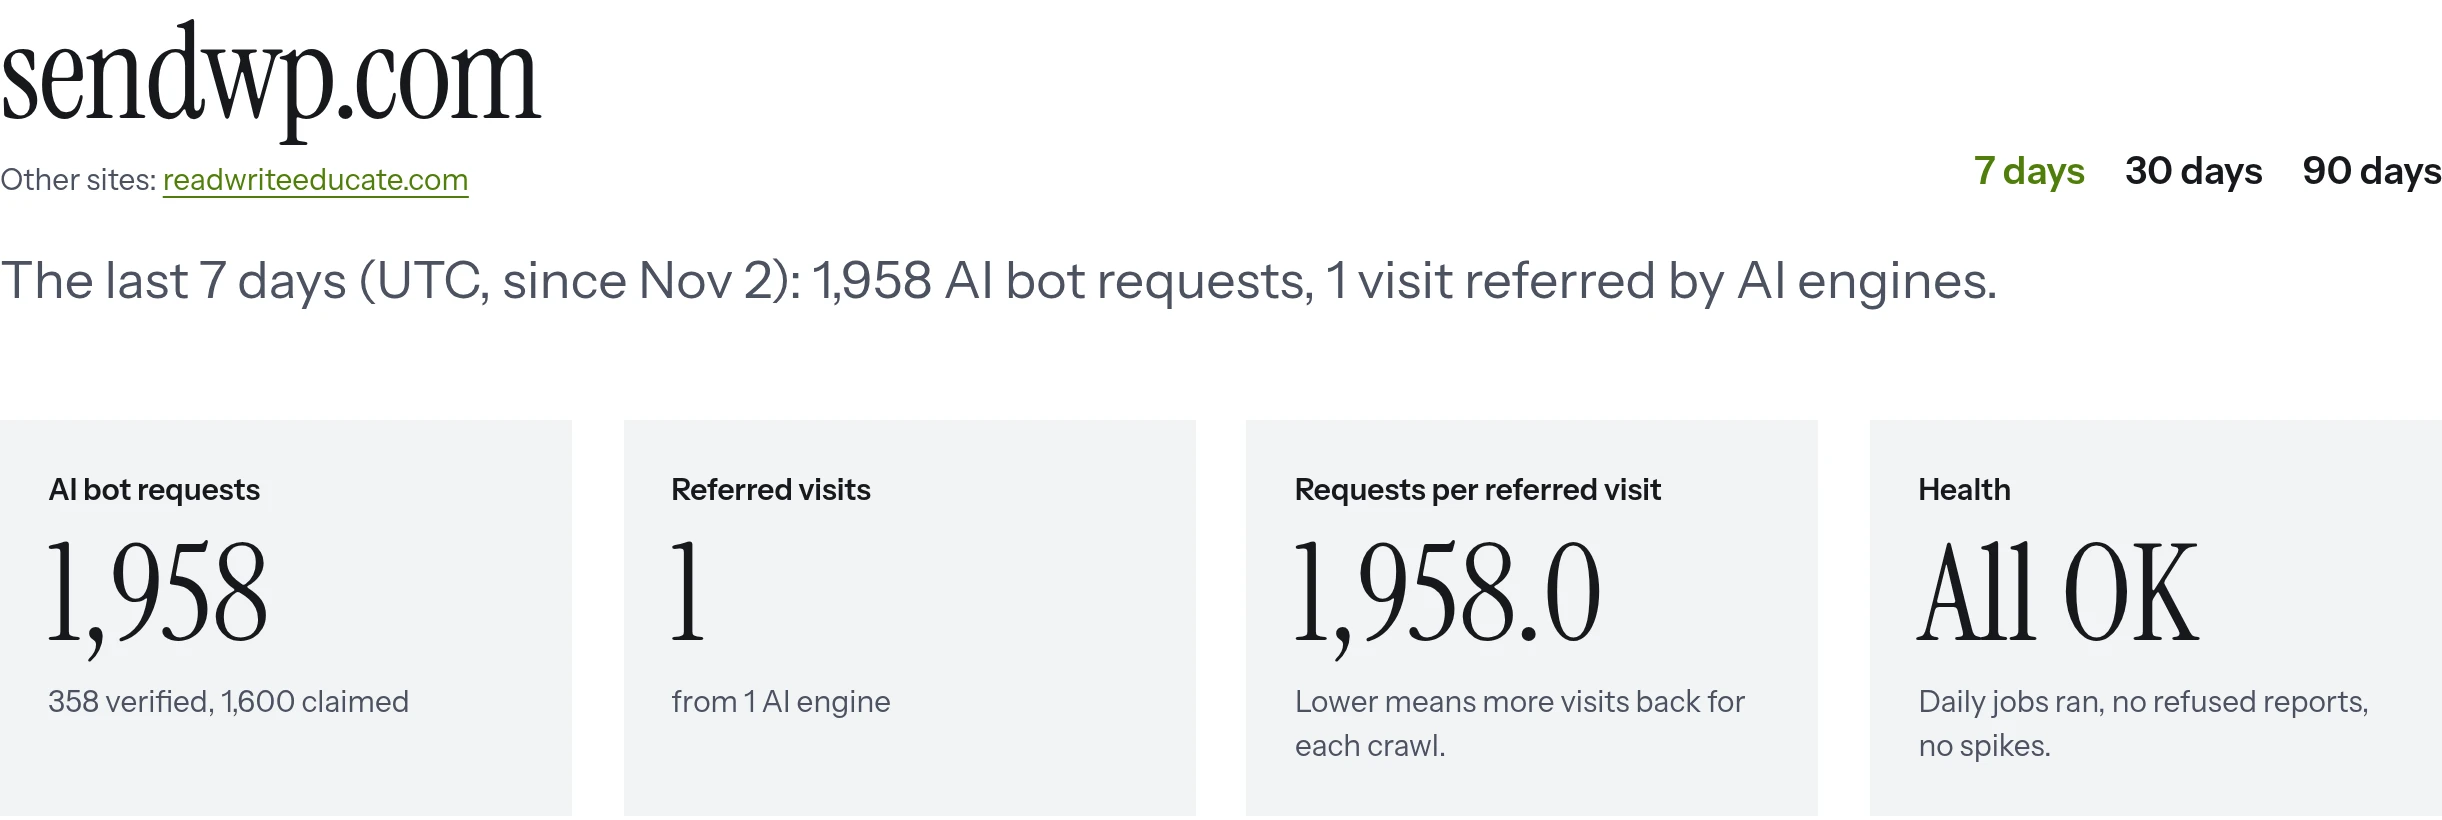
Your site at a glance
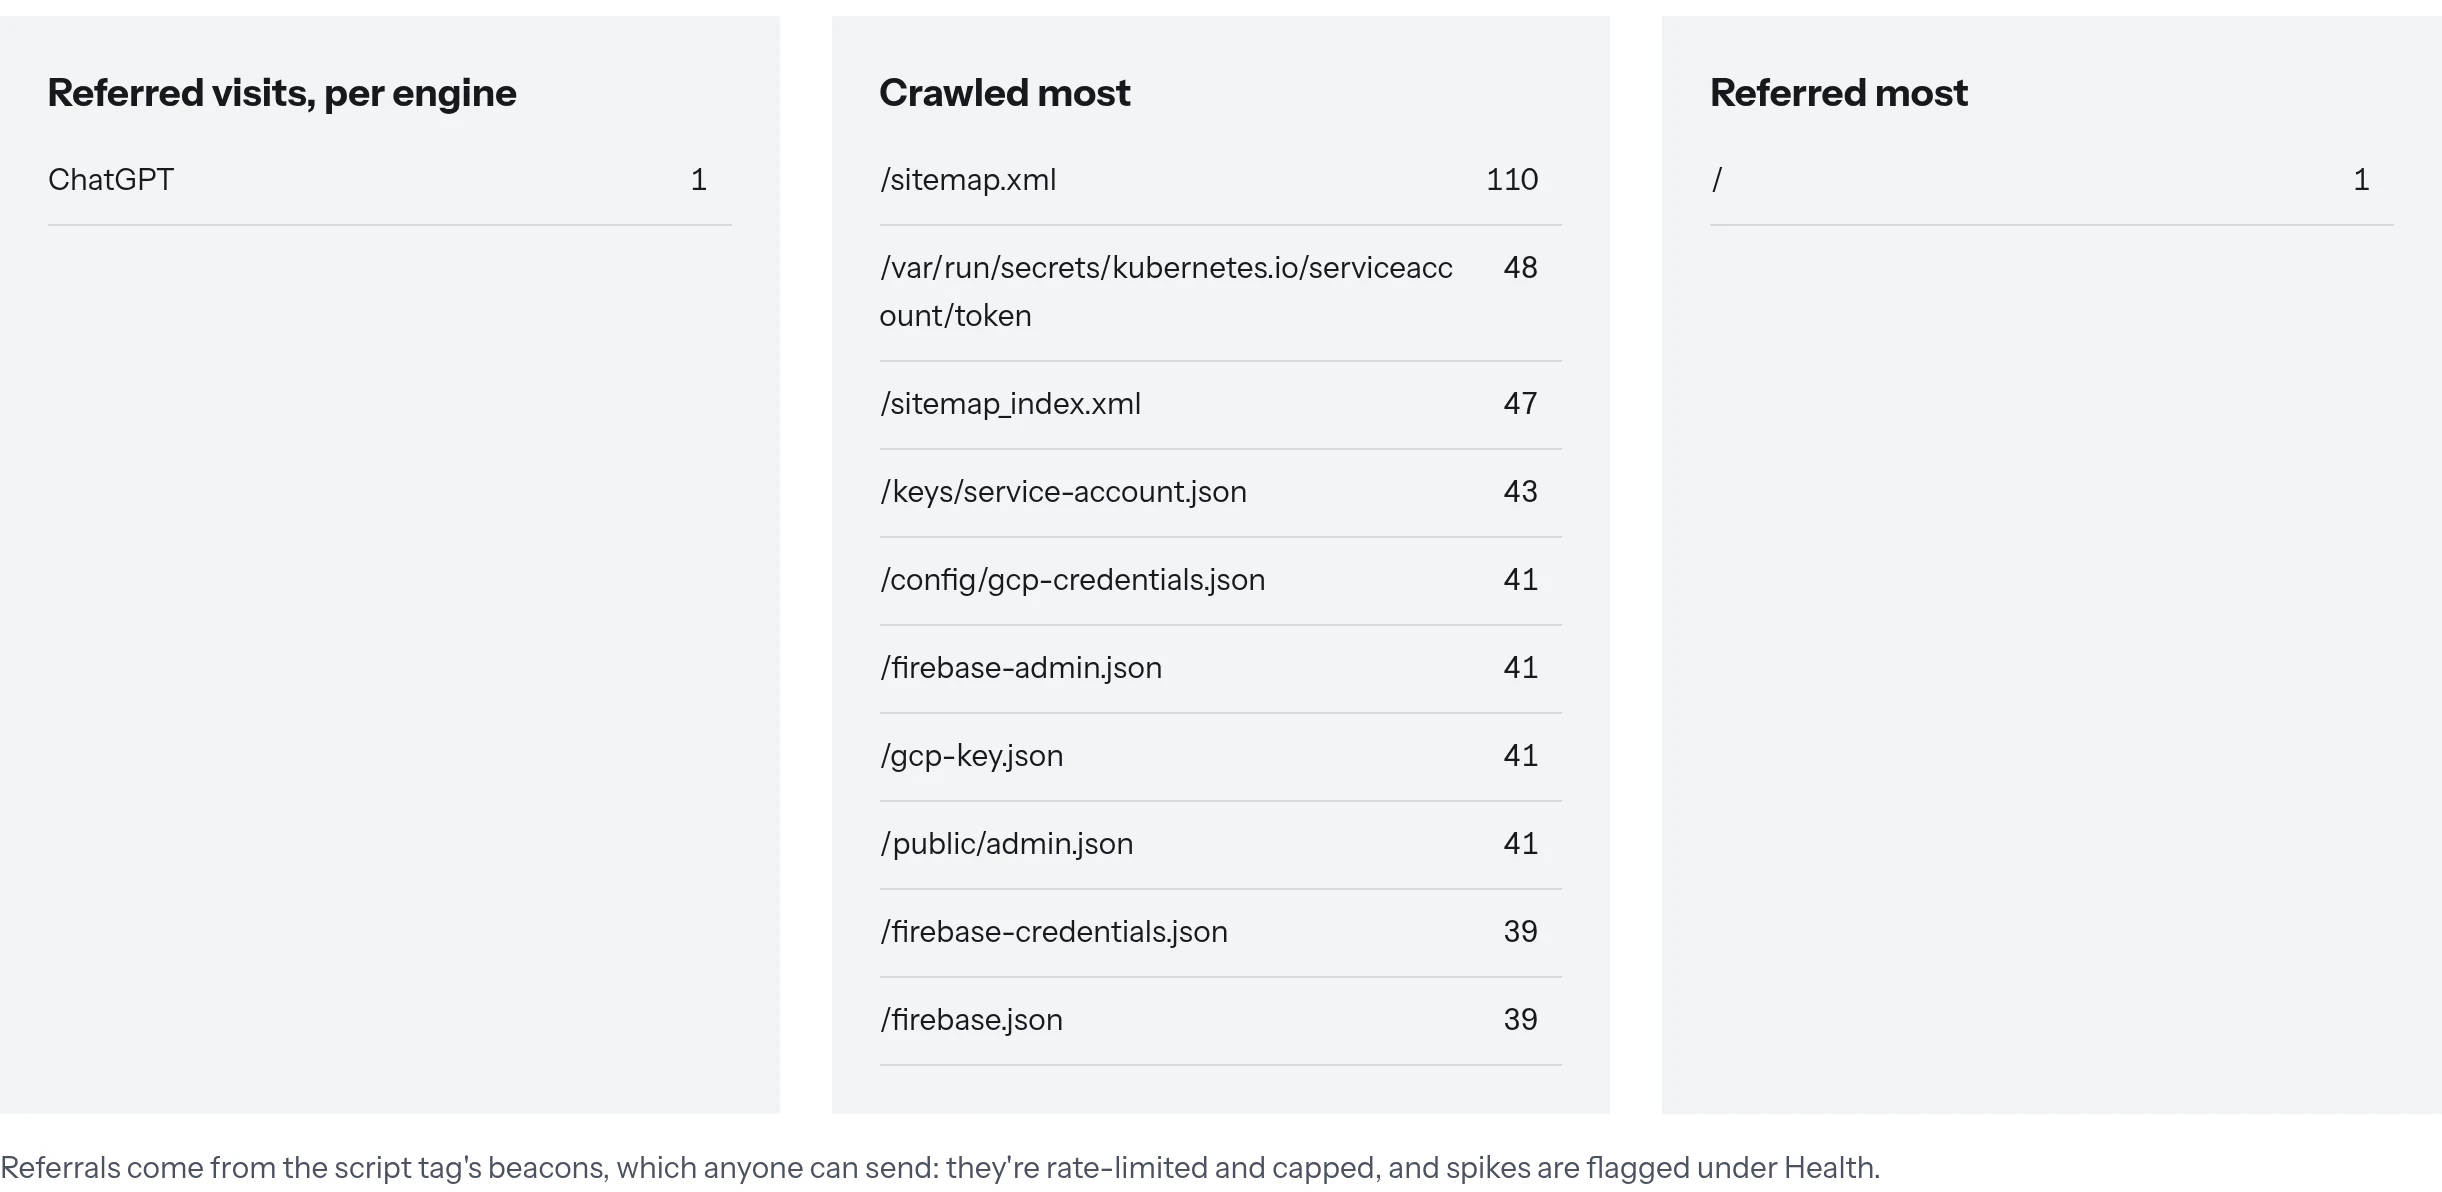
One page per site. Pick 7, 30 or 90 days. Every bot gets its crawls, how many were verified against the company's published list, and the visits its AI engine sent back.
Two small pieces, any stack
A script tag in your pages notices visitors who arrive from an AI engine. A reporter at your edge or on your server notices AI bots, with their real IP address, so each one can be checked. Both send only those requests, and nothing else, to aicrawlreport.com.
<script async src="https://aicrawlreport.com/t/v1.js" data-key="your-tag-key"></script>For the reporter: a Cloudflare Worker you deploy in your own Cloudflare account (any site behind Cloudflare, whatever runs it), one PHP file, or a Node/Express middleware.
In your visitors' browsers
- Spot a visit from an AI enginereferrer or utm
- Send one beacon: the page and the engine1 request
At your edge or server
- Match the user agent against 27 known AI botsno lookup
- Report that request, signed with your site's secret1 request
On aicrawlreport.com
- Check each bot against its company's IP listor by DNS
- Crawl requests and referred visits, per bot7, 30, 90 days
- Delete rows older than90 days
Cookies set on your visitorsnone
The bots it knows
-
GPTBot
Your call. It collects pages for training and sends no visitors itself. ChatGPT finds pages to cite through OAI-SearchBot, so blocking this one won't take you out of ChatGPT answers.
OpenAI · Model training · Checked against OpenAI's published IP list.
-
OAI-SearchBot
Allow. This is how ChatGPT finds pages to cite. The report shows it next to the visits ChatGPT sends you.
OpenAI · AI search index · Checked against OpenAI's published IP list.
-
ClaudeBot
Your call. It collects pages for training and sends no visitors itself. Claude finds pages to cite through Claude-SearchBot, so blocking this one won't take you out of Claude answers.
Anthropic · Model training · Checked against Anthropic's published IP list.
-
PerplexityBot
Allow. This is how Perplexity finds pages to cite. The report shows it next to the visits Perplexity sends you.
Perplexity · AI search index · Checked against Perplexity's published IP list.
-
Google-Extended
Your call. This is a robots.txt switch, not a crawler, so it never shows in the log: Google's normal crawler fetches your pages and this token decides whether they may be used for AI training. Blocking it doesn't affect your search listings.
Google · Model training · Never in the log: only robots.txt uses this name.
-
Bytespider
Consider blocking. It collects pages for AI training, and nothing it feeds sends referred visits. The plugin suggests blocking it once it has crawled your site.
ByteDance · Model training · ByteDance publishes no way to check, so its hits are marked claimed.
-
CCBot
Consider blocking. It collects pages for AI training, and nothing it feeds sends referred visits. The plugin suggests blocking it once it has crawled your site.
Common Crawl · Model training · Checked against Common Crawl's published IP list, with reverse DNS as a fallback.
-
Meta-ExternalAgent
Your call. It collects pages for training and sends no visitors itself. Meta AI finds pages to cite through Meta-WebIndexer, so blocking this one won't take you out of Meta AI answers.
Meta · Model training · Meta publishes no way to check, so its hits are marked claimed.
27 bots in all, and visits from 12 AI engines: ChatGPT, Perplexity, Gemini, Copilot, Claude, Le Chat, Meta AI, DeepSeek, Grok, Duck.ai, You.com, Phind. Type any name above to look it up.
Nothing about your visitors
The tag sets no cookies, uses no storage, and sends something only for visitors who came from an AI engine. People are counted as visits, never as visitors.
- For AI referrals we keep
- the time, the engine and the page. No IP address, no user agent, no cookie.
- For bot requests we keep
- the IP and user agent only when the bot is confirmed by its company's list or DNS. Unconfirmed ones are kept as "claimed", without either.
- How long
- 90 days, then deleted. The privacy page has the details.
On WordPress? Nothing has to leave your site
The free plugin does the same report inside WordPress, under Tools → AI Crawl Report. It writes every crawl and referral to your own database, checks the bots once a day, and never reports back to us. Pages served from a full-page cache never reach WordPress, so it can't count those.
Free · Version 1.0.0 · WordPress 6.4+ · PHP 7.4+ · GPL
Questions
What does my site need for the hosted tracker?
A place for one script tag in your pages, and one of: Cloudflare in front of the site (for the Worker, whatever runs behind it), PHP, or Node with Express. The tag counts visits from AI engines; the Worker or snippet reports AI bots with their real IP address, so each one can be checked. The privacy page says exactly what each sends.
Can I use it now?
The hosted tracker is in a private beta on our own sites. Join the waitlist and we'll email you once when it opens to more. On WordPress, the free plugin works today.
Does a referred visit mean a crawl got me cited?
No. Crawl requests and referred visits are counted separately. A referred visit is a person who clicked through from an AI engine; it is counted once for that engine and shown next to each of its bots. AI answers that cite you without anyone clicking through can't be seen from your site.
What does “claimed” mean?
Anyone can put “GPTBot” in a user agent. Hits are checked against the IP lists the AI companies publish, with reverse DNS as a fallback for Amazonbot and CCBot. A hit that can't be traced to its company is marked claimed. Meta, ByteDance, Cohere and some others publish no way to check, so their hits are always claimed, which doesn't prove they are fake.